
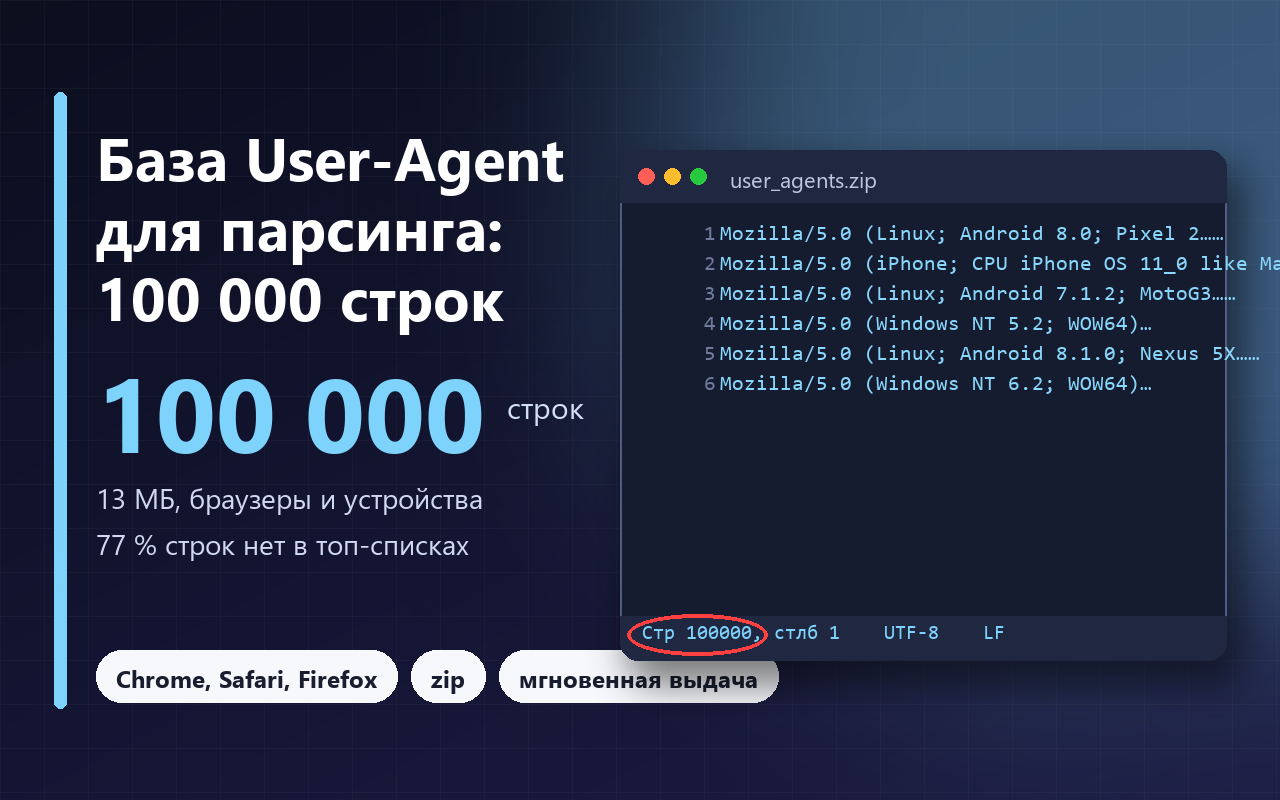
User-Agent database for parsing: 100,000 strings (browsers, OS, devices)
WHAT YOU GET
A 2 MB ZIP archive containing user_agents.txt: 100,000 lines, one User-Agent per line. 13 MB unpacked. UTF-8, LF line endings, no BOM. Every line is unique (case-insensitive check), no empty or broken entries. The archive is used because the marketplace rejects content files larger than 10 MB.
WHAT IT IS FOR
User-Agent rotation in scrapers and crawlers, anti-bot testing, load runs, client device analytics, test data, mobile/desktop redirect checks.
CONTENTS (counted, not claimed)
- Browsers: Chrome 56.8%, Safari 19.4%, Firefox 8.7%, Opera 3.8%, IE 11 1.6%, Edge 1.3%, Samsung Internet 1.2%, Yandex 0.5%, others (UC Browser, Pale Moon, Amazon Silk, WebViews) 6.7%.
- Operating systems: Android 57.1%, Windows 17.4%, iOS 8.8%, Linux 7.0%, macOS 6.4%, ChromeOS 0.4%.
- Devices: mobile 67.8%, desktop 32.2% (phones 54.2%, tablets 13.6%).
- 77% rare strings: they appear in none of the popular top-10000 lists, so the base does not repeat what you can find on the first page of search results.
WHAT IS NOT INCLUDED
Search engine and library strings (Googlebot, python-requests and the like) — only browser User-Agents that do not look suspicious to anti-bot systems.
HOW IT DIFFERS FROM FREE LISTS
Free sets hold 100 to 10,000 strings that everyone already has. This one has 100,000 lines collected from open datasets under permissive licenses (MIT, BSD, Apache) and deduplicated: out of 825,328 scanned lines 350,719 were unique, 100,000 made it into the file.
FORMAT AND DELIVERY
One User-Agent per line, ready for line-by-line reading in Python, PHP, Node.js or any other language. Unzip the archive and the file is ready to use. Available right after payment and later in your account.
No customer reviews yet.